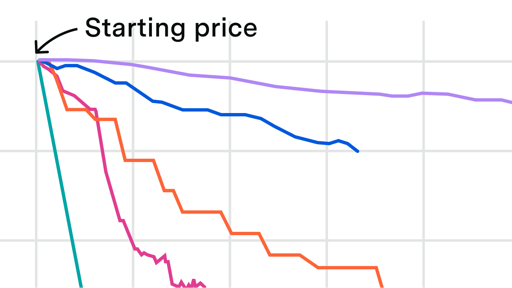
Epoch AI measures how fast the cost of a given level of AI performance is falling across five benchmarks covering math, science and games of skill: about 47% per quarter, or 13x per year, since 2023, faster than electricity, compute, batteries or DNA sequencing ever fell.
That works for “Mixture of Experts” models. These are basically models with distinct sets of weights and only a subset of them will be used on any particular query. The rest can sit on a disk.
It doesn’t work for dense models, where every weight is used all the time. There’s nothing inactive so a cache has nothing to exploit.
Yes, I believe it was for a Mixture of experts model, which just goes to show how naive IA implementations are at this point, The cache was not solving any hard problem and yet for some reason it was not only not already standard practice but also somehow a notable achievement.

That works for “Mixture of Experts” models. These are basically models with distinct sets of weights and only a subset of them will be used on any particular query. The rest can sit on a disk.
It doesn’t work for dense models, where every weight is used all the time. There’s nothing inactive so a cache has nothing to exploit.
Yes, I believe it was for a Mixture of experts model, which just goes to show how naive IA implementations are at this point, The cache was not solving any hard problem and yet for some reason it was not only not already standard practice but also somehow a notable achievement.